When many small businesses set up their systems for the first time, they face a long list of seemingly similar cloud configuration options. Should the region be Sydney or Singapore? Where should the database go? Where should the application server go? Where should object storage go?
If the only goal is to get the system running as quickly as possible, these choices are often treated as “just pick one for now.” And in many cases, that approach still works.
The problem is this: just because it works does not mean it is reasonable.
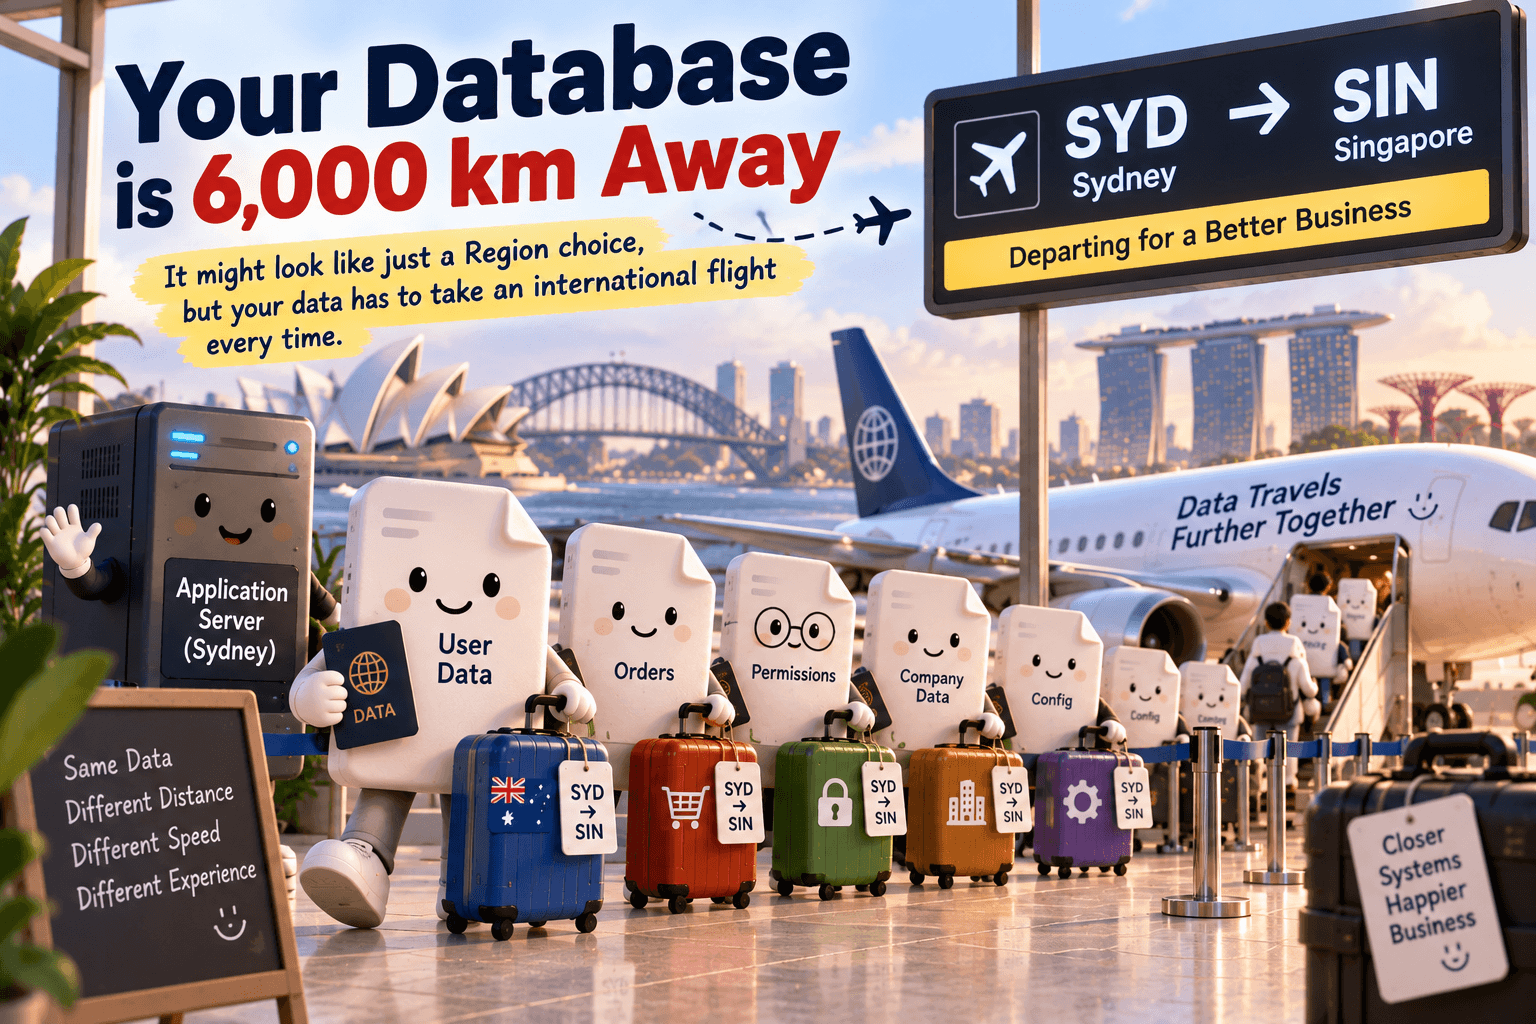
Recently, while investigating a production timeout issue, we encountered a classic example. The application server was in Australia. The main users were also in Australia. But the database was in Singapore. On the surface it looked like a simple region setting. In reality, the application server and the database were thousands of kilometres apart.
Background: The Database Was Already There
This project was not a green-field build. When we took over, the client already had a running application and an existing production database. That database held real business data and was already tied to the current system, accounts, and several third-party services.
The client also made a clear request: keep using the existing database for now. This is a common and reasonable requirement.
Migrating a production database is never as simple as exporting the data and importing it somewhere else. It can involve downtime windows, data consistency, account permissions, connection settings, third-party dependencies, rollback plans, and decisions about who can still write data during the move. In the early stages of the project, we therefore focused on stabilising the application itself — fixing features, cleaning up the code, improving the deployment process, and setting up clearer testing and production environments. The database continued to use its original configuration.
At the time it connected normally and could read and write without any immediately obvious problems. Only later, after a production incident, did we start asking a more fundamental question: where exactly is this database?
A Timeout Points the Investigation Toward the Database
One morning we received feedback from the client: many pages in the system had started returning timeout errors.
The first step was not to redesign the architecture. It was to reduce the impact on the business. We temporarily raised the timeout thresholds for some requests so that operations that previously failed could continue waiting instead of immediately returning an error to the user.
This was only a temporary stop-gap. If a page that should complete quickly now only succeeds because it is allowed to wait an extra ten or twenty seconds, the underlying problem has not disappeared. It has simply changed from “error after 10 seconds” to “might open after 30 seconds.”
As we continued investigating, a clear pattern emerged: the more complete the data and the more content a page needed to load, the more likely it was to time out. This naturally directed attention to the database.
We examined logs, query times, SQL, indexes, and some slow queries. The first reactions were the usual ones: Is the SQL poorly written? Are indexes missing? Are some joins too heavy? We optimised several clearly improvable areas. Some queries became a little faster, but the overall problem did not go away.
The database may still have had room for improvement, yet that alone could not explain the full latency we were seeing. At that point we began to consider another possibility: was the issue not that the database was “calculating slowly,” but that the application server and the database were “communicating slowly”?
Network Latency of 275 ms Reveals the Database Is in Singapore
We therefore tested the network latency directly from the application server to the database server. The result was approximately 275 ms.
For an ordinary user loading a web page, 275 ms on its own may not look dramatic. For high-frequency communication between an application server and a database, however, the number is concerning. An application and a database do not talk to each other only occasionally. Behind a single page there may be requests to read the user, check permissions, fetch company details, load subscription status, retrieve business data, query related records, and then read configuration.
When these operations have sequential dependencies, every round-trip adds more network latency.
We then checked the database’s own deployment information. After logging into the client’s existing Supabase dashboard, we saw:
Region: Singapore
The application server was in Australia. The primary users were also in Australia. Suddenly many of the earlier symptoms made sense.
The actual request path looked more like this:
Australian user → Application server (Australia) → Cross-region network → Database (Singapore) → Cross-region network → Application server (Australia) → Australian user
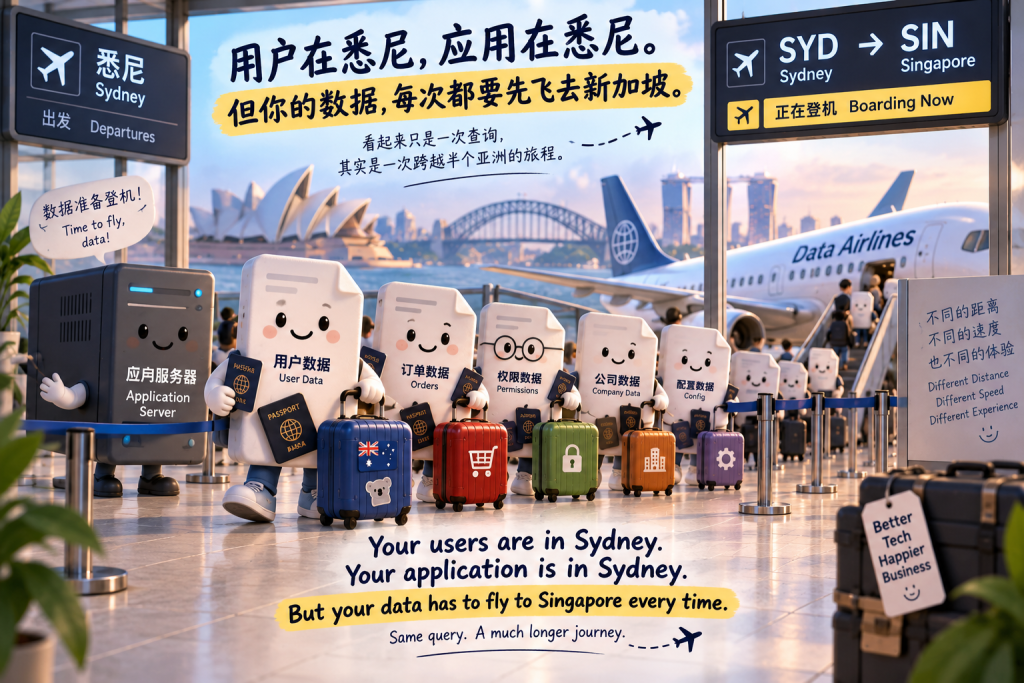
The straight-line distance between Sydney and Singapore is more than 6,000 kilometres. After a user in Sydney opens a page, the backend data requests may be travelling back and forth between Australia and Singapore repeatedly.
We thought we were investigating a database performance problem. What we discovered was that the application server and the database were separated by “ten thousand miles.”
Why “Only Tens of Milliseconds” Turns into Seconds or Timeouts
This is the point that confuses many non-technical users the most. If a single cross-region database call only adds tens of milliseconds, it hardly seems worth worrying about.
The difficulty is that a page rarely makes only one database call.
For example: Query A → Query B → Query C → Query D → Query E. If every query could run fully in parallel the impact would be smaller. In real business logic, however, dependencies are common. You first need to know who the user is before you can check their permissions. Once you have the permissions you can find which companies they can see. After that you still need to load the corresponding data and configuration.
So tens of milliseconds are added to tens of milliseconds, and then to more tens of milliseconds. On top of that come the database’s own execution time, application logic, third-party APIs, and front-end rendering. What the user experiences is no longer “a few dozen extra milliseconds.” It becomes “why is this page always spinning?” In more serious cases it becomes a timeout error.
This is also why the distance between the application and the database is usually more sensitive than the distance between an ordinary user and a web page.
| Scenario | Impact of a Single Round-Trip | Actual Page Experience |
|---|---|---|
| Same region (Australia ↔ Australia) | Low | Smooth, almost unnoticeable |
| Cross-region (Australia ↔ Singapore) | About 200–300 ms | Multiple queries easily accumulate into several seconds |
| Plus slow queries or missing indexes | Higher | Directly triggers timeouts |
The Most Dangerous Problems Are Often the Ones That Still “Work”
If a wrong database region made the system completely unusable on day one, the situation would actually be easier to handle. Everyone would immediately know something was broken.
The real difficulty arises when everything continues to work. Logins succeed. Pages eventually load. The database dashboard stays green. CPU is not maxed out. The server has not crashed. From the cloud platform’s own perspective, everything even looks normal.
Problems of this kind can therefore remain in the system for a long time. Months later people start noticing the site feels a little slow. Then the questions begin: Is React too slow? Is Java too heavy? Is PostgreSQL not fast enough? Is the server under-provisioned? Should we add Redis? Should we upgrade the plan?
With AI coding tools now available, these issues can also be rapidly over-complicated. A simple request — “the site is a bit slow, please optimise it” — may result in caching layers, asynchronous jobs, message queues, microservices, or even database sharding. The real problem may simply be that the database is too far away.
Sometimes a system does not need more technology. It only needs the things that should be close to each other to be placed close together.
Many software problems in small businesses fall into exactly this category. They are not the result of the system being completely neglected, nor of someone necessarily making a “wrong decision.” They are the result of an early choice made for the sake of speed, risk reduction, or continuity with an existing system — a choice that was never re-examined later.
Regions Are Not Chosen at Random, but That Does Not Mean You Need “Enterprise Architecture”
The cloud does not mean servers float in a location-free space. Cloud servers ultimately run in real data centres — Sydney, Singapore, Tokyo, Frankfurt, Virginia. These regions are not merely convenient labels in a control panel. They represent physical data-centre locations, network paths, and sometimes data-compliance and availability considerations.
That does not mean every Australian company must place everything in Sydney. If a company’s customers are mainly in Southeast Asia, Singapore may be entirely reasonable. If the business is global, a CDN, edge network, or even multi-region deployment may eventually be needed once scale justifies it. If the data involves healthcare, finance, government, or other sensitive categories, data residency, contracts, and regulatory requirements also come into play.
So the real question is not “Is Singapore good or bad?” It is “Why did this system choose Singapore?”
- If the answer is “our main users are there,” that is fine.
- If the answer is “it is a compliance requirement,” that is also fine.
- If the answer is “we don’t know — it was the default at the time,” then it is worth re-checking.
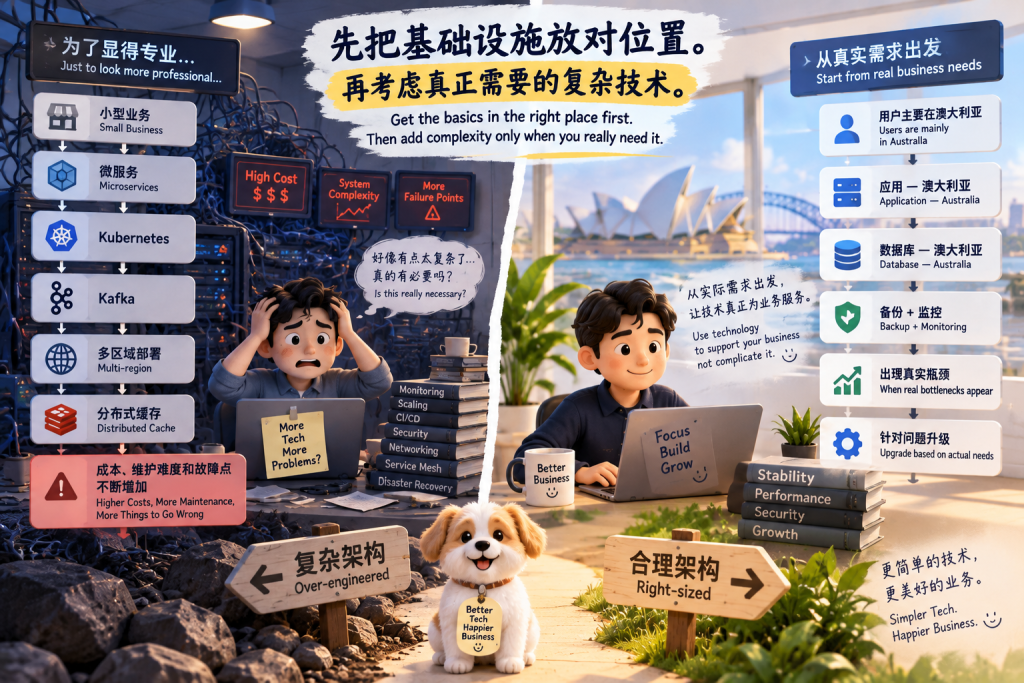
Likewise, a small business should not swing to the opposite extreme the moment a region issue is discovered: one set in Sydney, one in Singapore, one in the United States, followed by Kubernetes, Kafka, multi-region databases, and distributed caches all at once.
For a company of a dozen people, what is often truly needed is simply:
Main users in Australia → Application in Australia → Database in Australia → Object storage / CDN
Together with basic backup, monitoring, a staging environment, logging, permission management, and failure notifications, this already solves a large number of practical problems.
Reasonable architecture ≠ complex architecture.
“The System Runs” and “Someone Is Looking After the System” Are Two Different Things
For non-technical owners it is not easy to judge whether a system is actually healthy. The website opens. Staff can log in. SSL is valid. The database is online. Dashboards are all green. From a business perspective it is natural to conclude that everything is fine.
Real software operations look at a different layer. For example: Where are the application server and the database located? Are the database connections reasonable? Are there obvious slow queries? Can backups actually be restored? Are staging and production properly isolated? Where is object storage? Are staff and contractor permissions excessively broad? Who receives a notification when a service goes down? Does anyone know when the disk is nearly full? When a third-party service fails, does the user see a friendly message or an internal server error?
These issues rarely appear on the home page, yet they determine whether a software system is merely “still running” or is genuinely being maintained.
The incident ultimately prompted us to re-examine more than just the database region. It served as a reminder: launching software does not mean the technical work is finished. Systems that have been running for some time, passed through different developers, external teams, temporary changes, and even AI-generated code, tend to accumulate historical decisions of this kind.
Some problems are genuinely complex. Some require code changes. Some may need a database redesign. Many others, however, simply have never been paused long enough for someone to ask:
“Why was this configuration chosen in the first place?” and“Is it still reasonable today?”
The software health checks, system remediation, and ongoing operations services offered by Snowsy are not intended to turn a small business into an “enterprise-scale architecture.” In many cases the work is the opposite: we start by examining the most basic, most easily overlooked issues that actually affect performance, stability, and data security. It may be a database connection, a backup, permissions, an uncontrolled background job, missing monitoring — or simply the fact that your application server and database are separated by ten thousand miles.
If your system has been live for some time but has never received a systematic review of servers, databases, backups, permissions, monitoring, and deployment practices, Snowsy can also begin with a lightweight software health check. There is no need to rewrite everything, and no need to introduce more technology than necessary. First find the real problems, then decide what is worth changing.